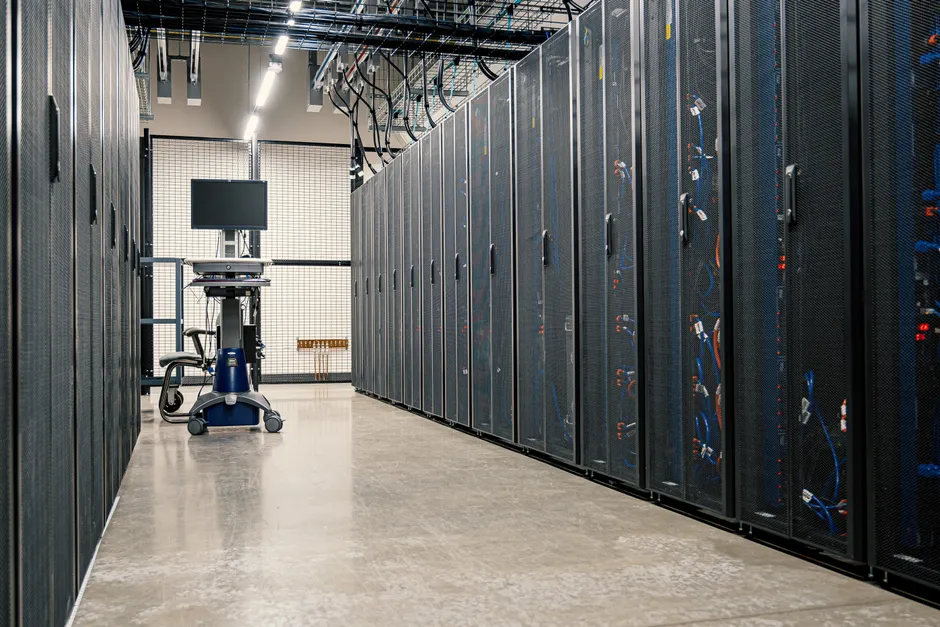
Cerebras CEO to Tackle AI Scaling Limits at TechCrunch Disrupt 2026
Cerebras Systems CEO and co-founder Andrew Feldman will speak on the Disrupt Stage at TechCrunch Disrupt 2026 in a session titled "Can AI Keep Scaling?" TechCrunch
The conference is scheduled for October 13-15, 2026 at Moscone West in San Francisco. Feldman's session will address growing demand for compute, energy and infrastructure and how Cerebras is approaching those constraints.
Feldman co-founded Cerebras in 2015. Before that, he co-founded and led microserver startup SeaMicro, which AMD acquired in 2012. He also held leadership roles at Force10 Networks and Riverstone Networks.
That networking and systems background matters for the topic at hand. Scaling AI is now as much a problem of cluster architecture, interconnect and power delivery as it is of model design. Practitioners feel it in procurement cycles, data center fit-outs and long-lead utility planning.
Cerebras provides AI compute through on-premise systems and its cloud platform. Its core hardware approach is a processor built on the silicon wafer itself rather than cutting a wafer into individual chips, designed for AI workloads. In August 2026, the company introduced CS-4, the latest generation of its wafer-scale AI infrastructure. TechCrunch
Two recent business points frame the session. Cerebras raised $5.5 billion in its May IPO before September 30, 2026. It also signed a multiyear agreement with OpenAI to deploy 750 megawatts of Cerebras systems from 2026 through 2028. TechCrunch
The broader context here is that compute, energy and infrastructure can no longer be treated as separate discussions. For enterprise and cloud operators, wafer-scale integration changes the usual tradeoffs around die-to-die interconnect, memory locality and system-level yield. It also concentrates power and cooling requirements in ways that simplify some aspects of cluster design while making site selection and power provisioning more demanding.
In my view, that is the right question for Disrupt to put on its main stage. Much of the public debate about scaling still focuses on parameter counts and training budgets. The operational questions are less visible but more binding. Where does firm power come from. How quickly can systems be installed and kept fed with data. Which workloads stay on premises for control or latency reasons and which move to shared cloud capacity.
Looking at what this means for technology leaders, the OpenAI capacity commitment and the CS-4 refresh give Feldman concrete material to work with. A 750-megawatt deployment plan spanning three years is not a laboratory experiment. Power is now the constraint. Deployment velocity matters. For architects evaluating accelerators, the relevant comparison is total throughput per rack and per megawatt under production inference and training mixes, plus the operational cost of getting there.
Worth flagging for a technical audience is the delivery model split. On-premise systems and cloud access imply different scaling paths. One favors organizations with secured power and a need for data control. The other favors teams that need burst capacity without building new facilities. How Cerebras balances those paths, and what it has learned supporting both, should be useful detail beyond the usual scaling rhetoric.
The agenda also includes a Builders Stage covering fundraising, hiring, product-market fit and scaling. That programming is aimed at early-stage operators, while the Feldman session speaks directly to infrastructure decision makers.
If scaling continues, it will be because systems, power and software were co-designed to allow it. That outcome is not guaranteed, but it is achievable. Expect a pragmatic discussion about what it takes to keep building.